Paper verified
冻结模型
没有训练扩散网络。文本实验用 Stable Diffusion 1.4;人脸实验用 CelebA-HQ 256 无条件扩散模型与 ArcFace;风格实验用 CLIP 第三层特征 Gram reward。
Effective and Flexible Diffusion-Based Editing via Doob's h-Transform
论文把冻结扩散模型上的图像编辑写成反向时间桥问题,以 Doob \(h\)-transform 分离“重建基底”和“编辑增量”。理论给出理想桥的边际分布;实际算法使用固定 inversion 起点、有限步 Langevin 类更新与近似 reward score,因此必须区分精确定理、作者近似和代码行为。
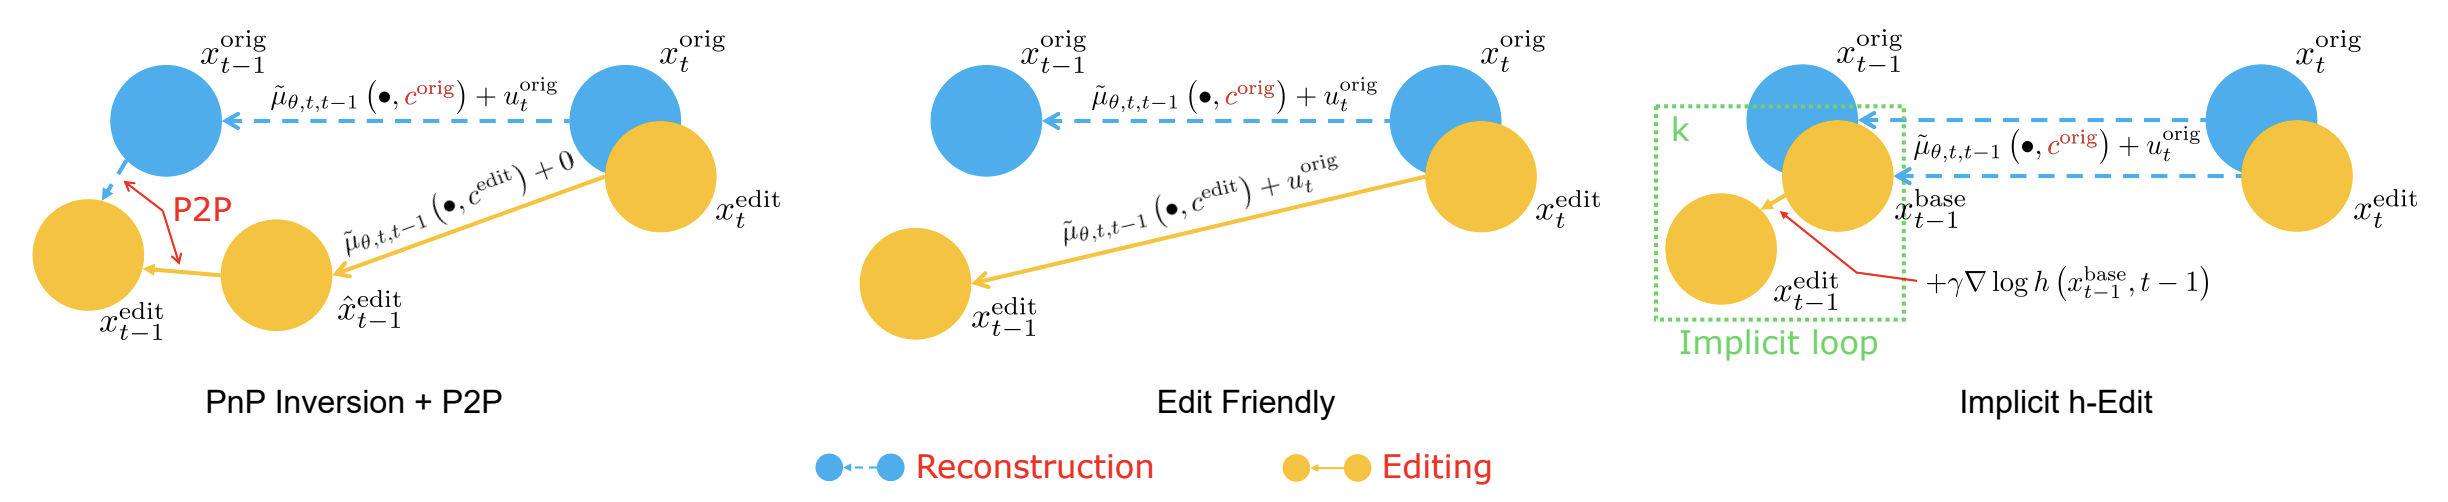
既有 training-free 方法多从 inversion 或 attention control 改善重建,缺少同时容纳文本条件、外部 reward 和多目标组合的统一表达。h-Edit 把每一步写成基底 \(x^{\mathrm{base}}_{t-1}\) 加 \(h\)-score 编辑项,使 deterministic / random inversion、P2P、MasaCtrl、PnP 以及视觉 reward 进入同一框架。
没有训练扩散网络。文本实验用 Stable Diffusion 1.4;人脸实验用 CelebA-HQ 256 无条件扩散模型与 ArcFace;风格实验用 CLIP 第三层特征 Gram reward。
显式形式在 \(x_t\) 评估 score;隐式形式先得到 \(x^{\mathrm{base}}_{t-1}\),再在 \(t-1\) 状态执行一个或多个 inner-loop。
定理要求 harmonic \(h\) 和倾斜初分布。实际固定 \(x_T^{\mathrm{edit}}=x_T^{\mathrm{orig}}\),reward 又通过 Tweedie 均值近似,输出没有一般性的精确目标分布保证。
基础反向链为 \(p(x_{t-1}\mid x_t)\)。\(h(x_t,t)\) 应为非负、在相关支持域上严格为正且可积。论文令 \(h(x_0,0)=p_Y(x_0)\);严谨语义是目标属性的未归一化权重或 likelihood,额外归一化后才成为概率密度。
第二式负责归一化,并由 Chapman-Kolmogorov 得到 \(h(x_t,t)=\mathbb E_{p(x_0\mid x_t)}[h(x_0,0)]\)。Appendix A.1 末尾积分变量存在排版误写,按 \(x_{t-1}\) 才与推导一致。
论文把固定时刻 LMC 更新改写成跨 \(t\rightarrow t-1\) 的扩散更新,并把基础 score 合入 \(x^{\mathrm{base}}_{t-1}\)。VP drift、跨时间系数和原图残差使它只构成近似类比。
score 在当前状态评估;Eq. 13 把固定时刻更新用作跨时间转换。
“隐式”表示在下一状态计算并允许重复更新,没有精确求解一般 implicit SDE。正 \(\gamma\) 不改变全局 argmax;有限步、步长、初始化和重建正则形成实际权衡。
\(\eta=0\) 对应 deterministic DDIM,\(\eta=1\) 对应 DDPM 型随机采样。
采用论文统一记号 \(\bar\alpha_t=\prod_{s=1}^{t}\alpha_s\),并定义
广义 DDIM/DDPM reverse mean 和 noise coefficient 写为
确定性路径取 \(\eta=0\),所以 \(\sigma_{\eta,t,t-1}=0\);随机路径取 \(\eta\gt0\),并在均值外保留 \(\sigma_{\eta,t,t-1}z_t\)。两类 reconstruction base 分别为
文本编辑函数必须保留 original、target 与 unconditional 三个 prediction 的权重差:
显式关系使用当前时刻的 \(\sigma_t\):
隐式关系使用下一状态和 \(\sigma_{t-1}\):
严格正号只适用于对应 \(\sigma\gt0\) 的更新时刻。最后 \(t-1=0\) 时 \(\sigma_0=0\),官方 face 实现将 inner-loop 数设为零。\(w_{\mathrm{orig}}\) 只控制 base CFG,\(\widehat w_{\mathrm{orig}}\) 控制编辑增量,两者不能混同。
target 与 original prompt 的 noise 差近似两项;\(\hat w_{\mathrm{orig}}\) 调节减去多少原图语义。
非线性 reward 满足 \(\mathbb E[h(x_0,0)\mid x_t]\neq h(\mathbb E[x_0\mid x_t],0)\)。梯度通过 VAE 与 ArcFace/CLIP/LPIPS,不通过 UNet。
论文用于多次更新回拉;代码改用 L1 gradient 与 RMS 归一化,\(K=1\) 时不执行 shrink。
score 可相加;多个 harmonic \(h_i\) 的乘积一般不再 harmonic,组合仍是实用近似。
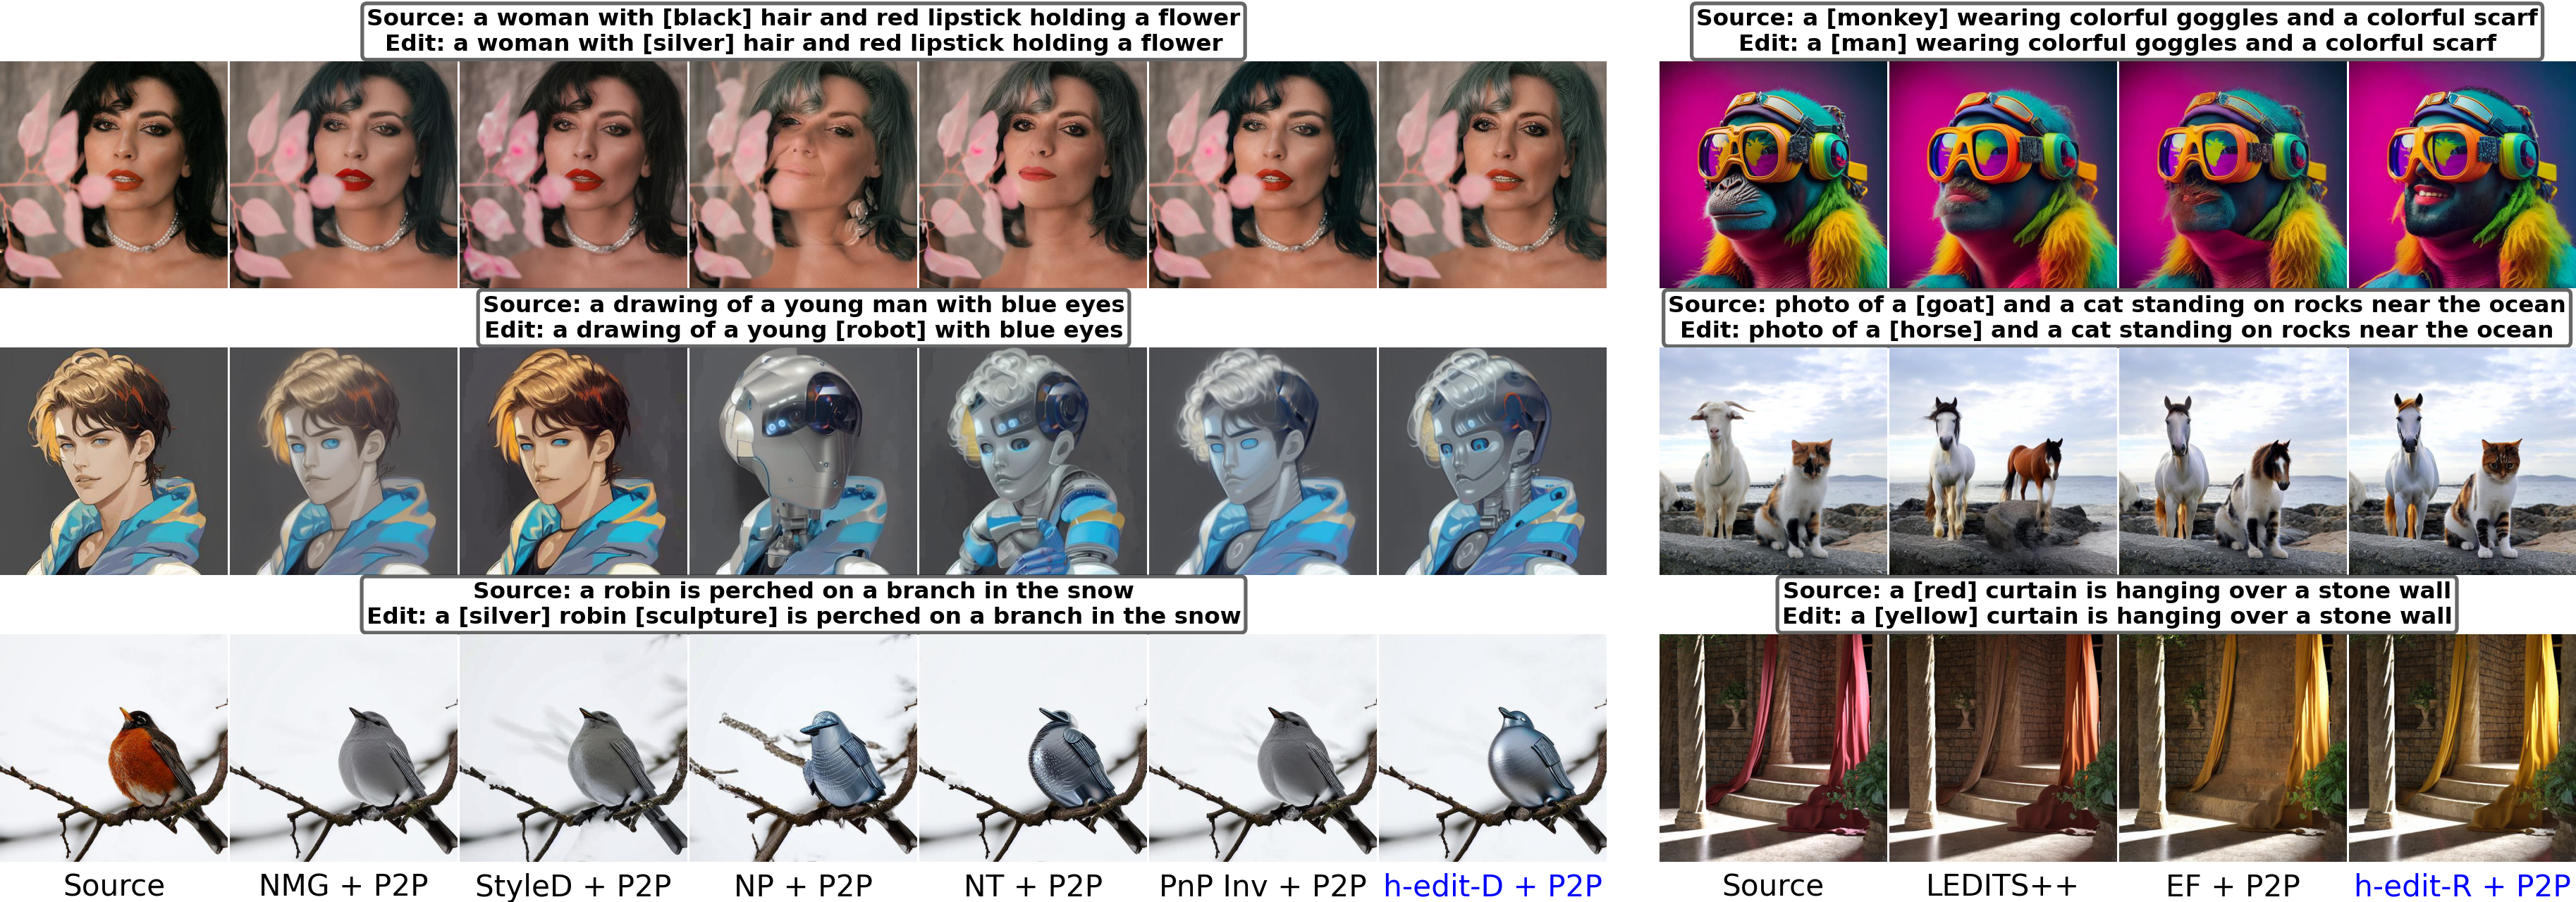
SD1.4,50 steps。PIE-Bench 700 图、10 类编辑;mask 只用于背景指标。h-Edit-D 权重为 \((1,10,9)\),h-Edit-R 为 \((1,7.5,5)\)。P2P self/cross fraction=.6/.4;random/EF self=.35。
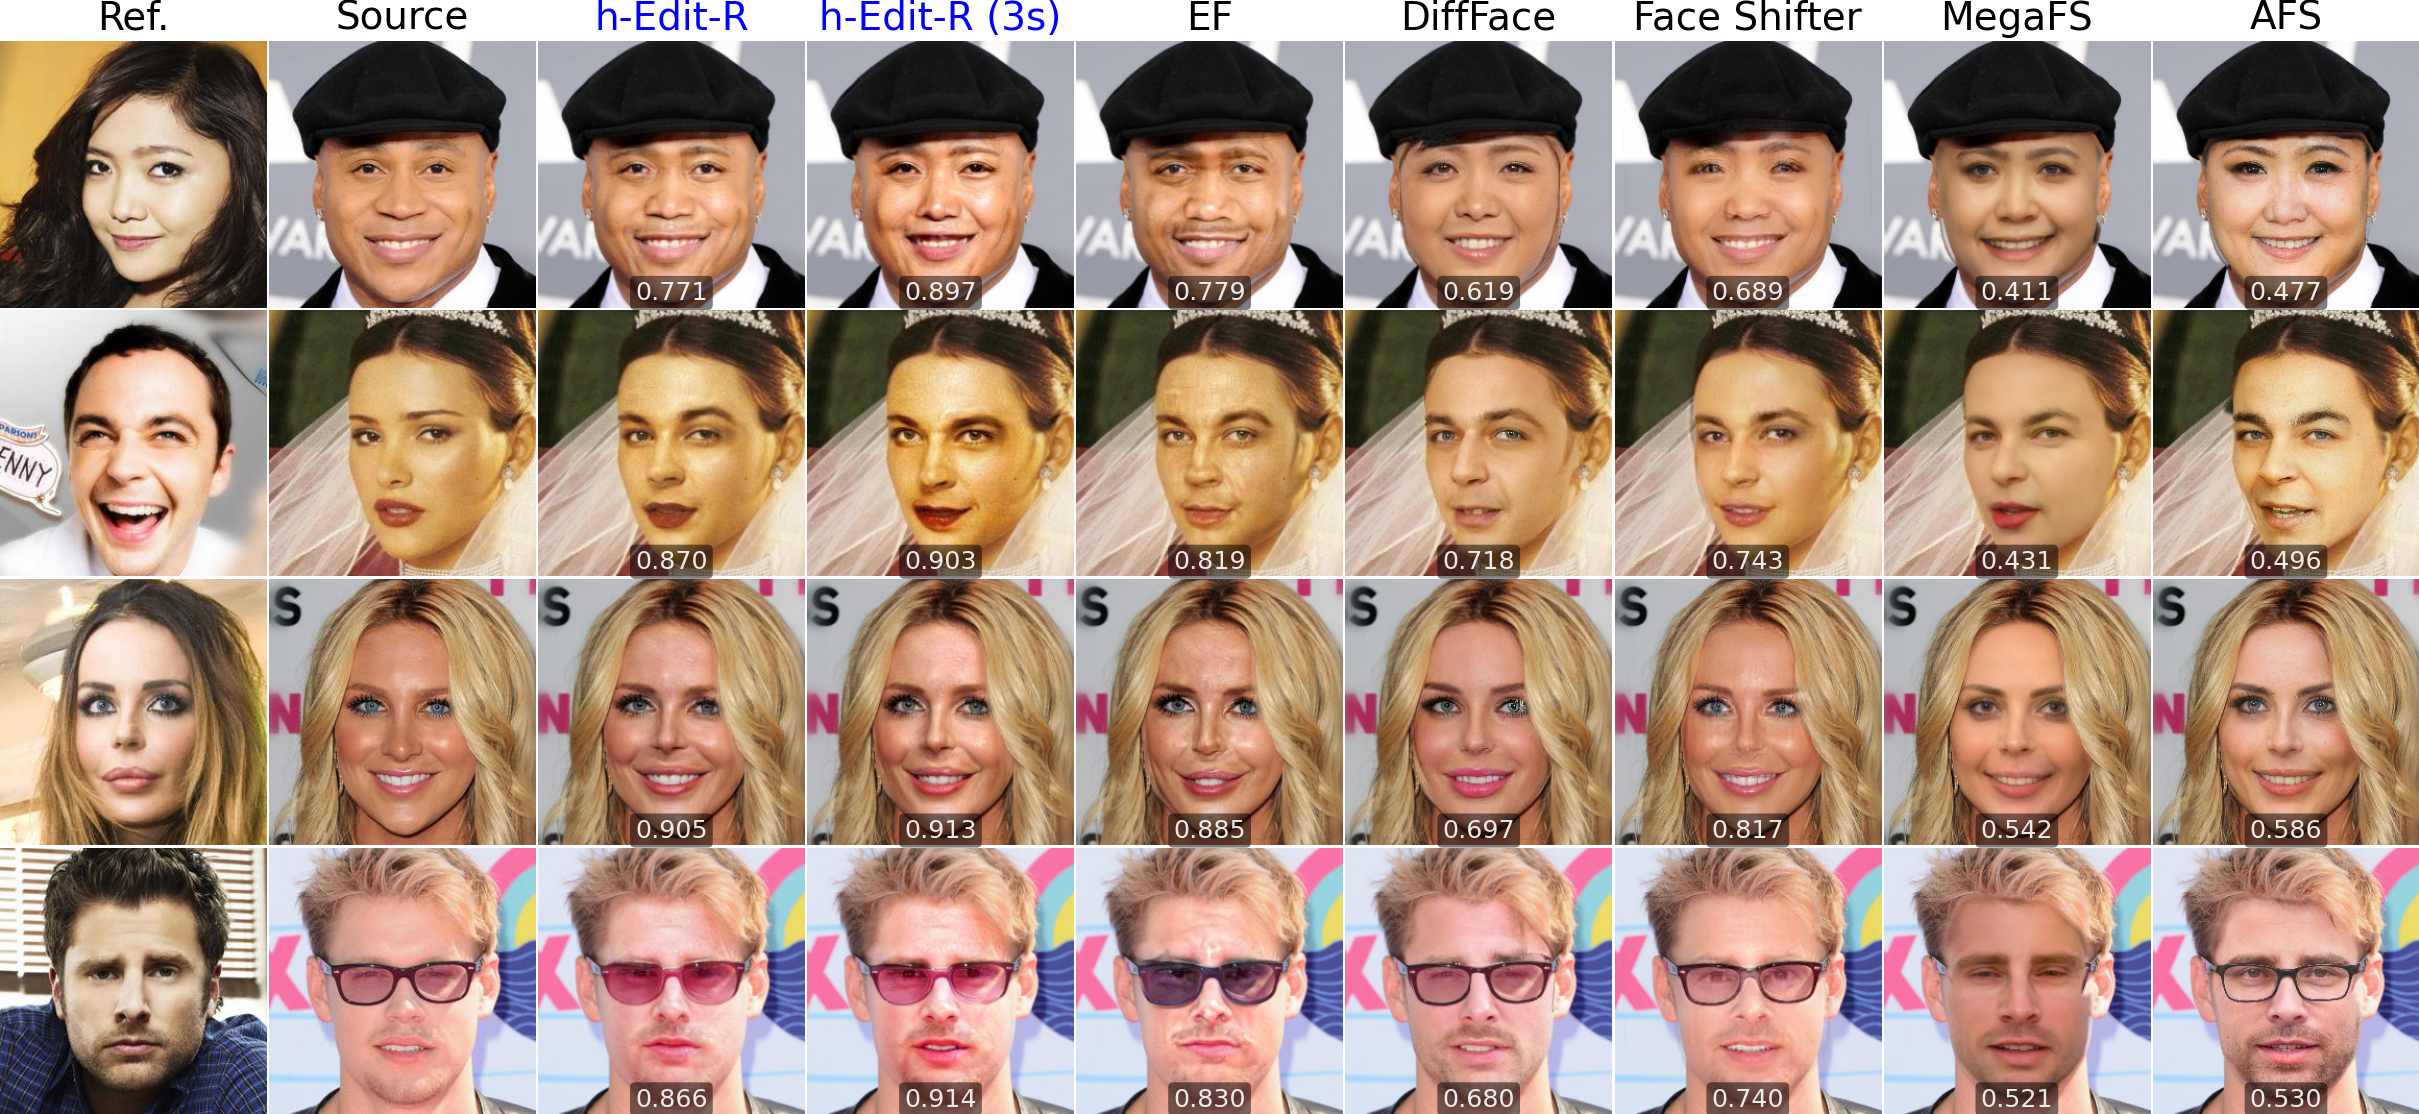
CelebA-HQ 256,100 steps,5,000 对。ArcFace IR-SE-50 同时作 reward 和主 ID 指标,另加负 LPIPS-VGG reward。裁切 \([35{:}223,32{:}220]\)。\(\rho_t=\rho_{\mathrm{face}}\sqrt{\bar\alpha_t}\):1-step/EF 为 100,3-step 为 50;最后 mask 恢复背景。
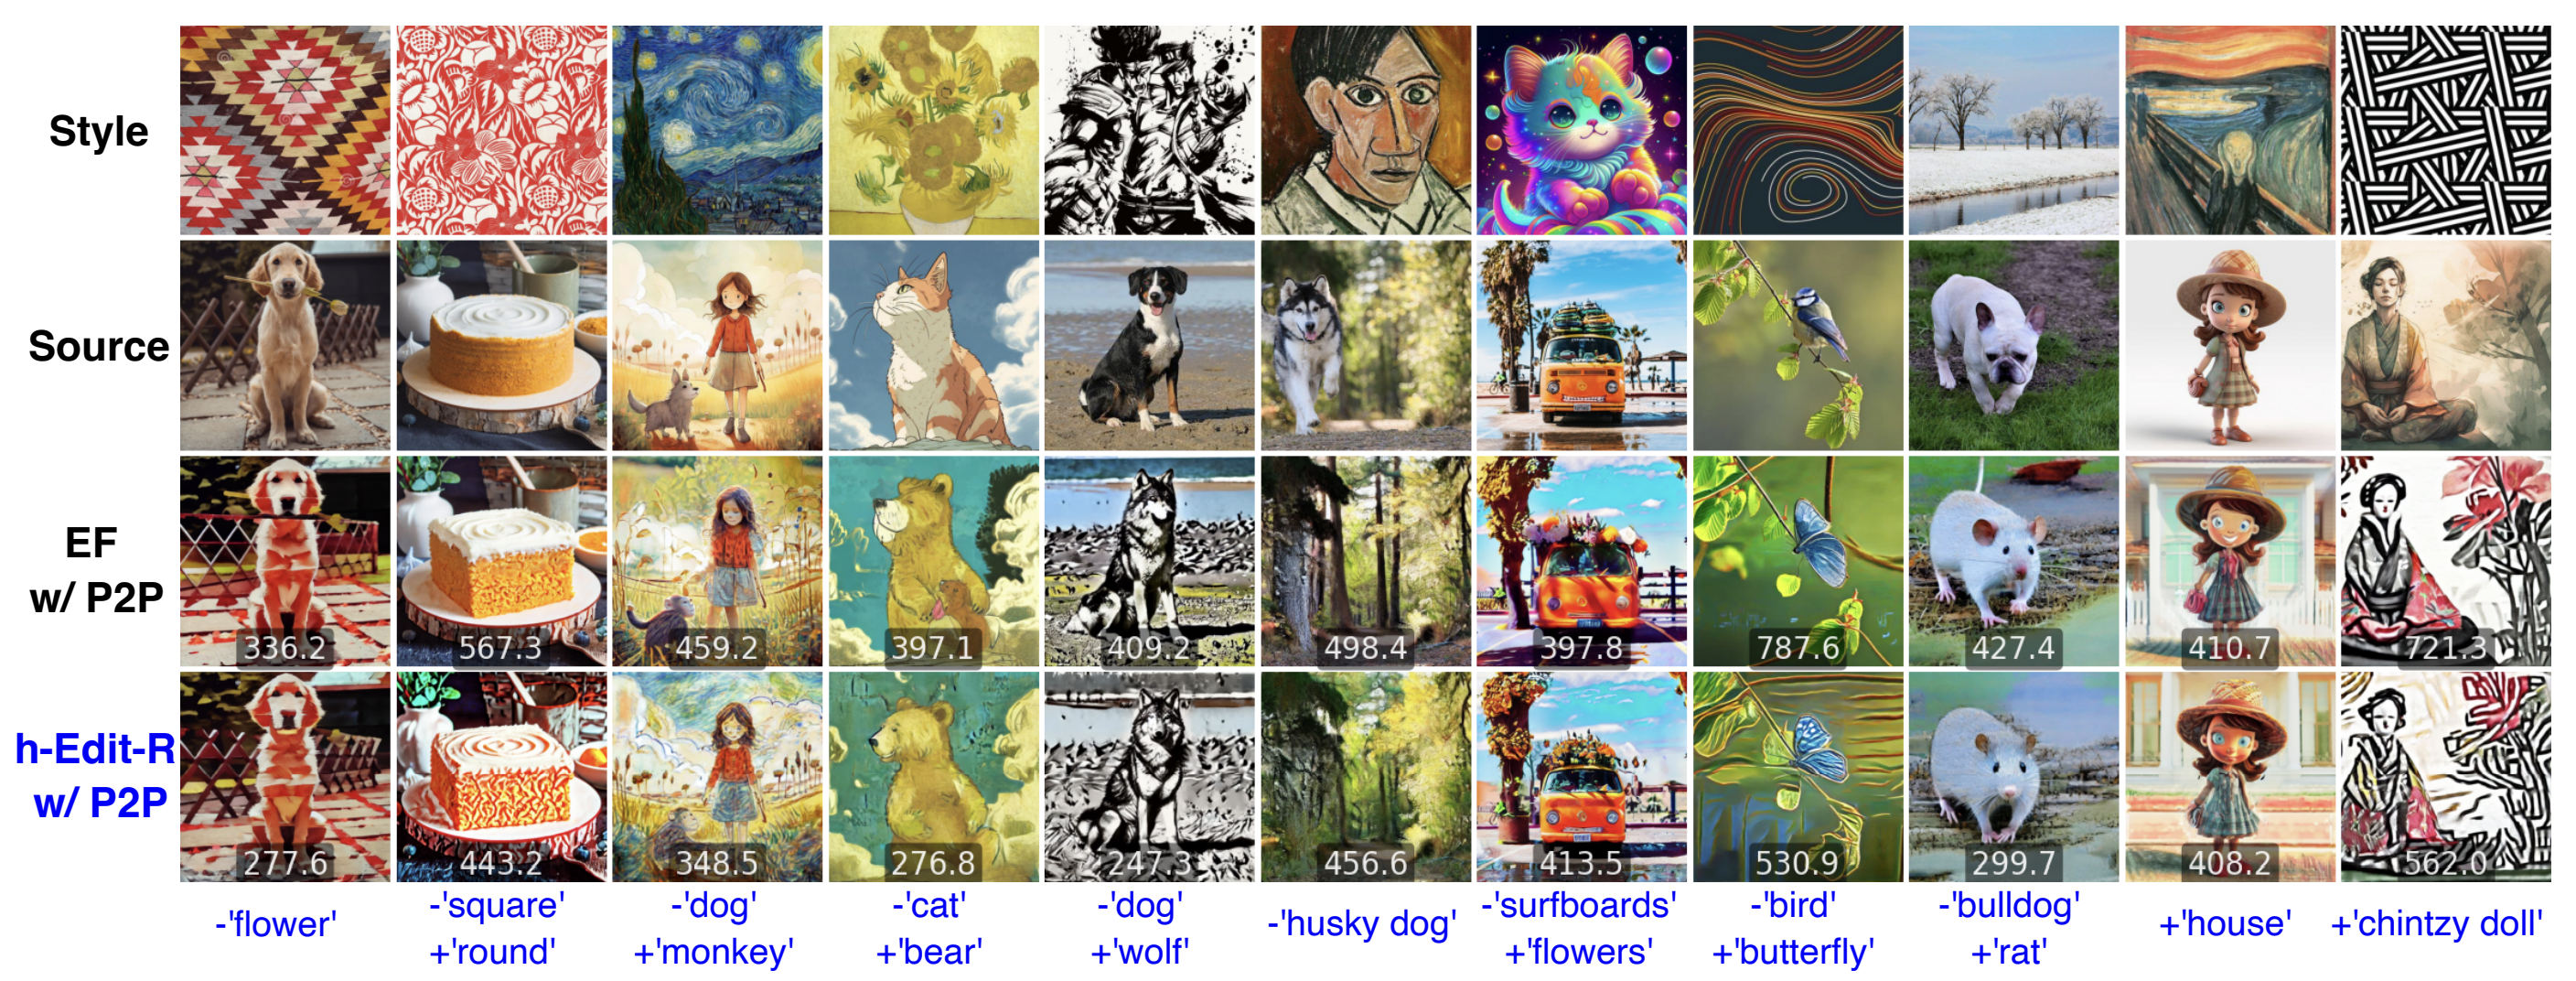
每图随机配 11 种 style 之一。CLIP 第三层 feature Gram 的负 L2 为 reward,梯度范数与文本增量一致。h-Edit/EF 的 style 权重分别 .6/1.5,来自视觉调参;关闭 local blend,主要提供 qualitative 证据。
CLIP、Local CLIP、SSIM、PSNR 越高越好;DINO、LPIPS 越低越好。DINO/LPIPS 已乘 100,SSIM 已乘 10。
| Inv. | Attn. | Method | CLIP | Local | DINO×100↓ | LPIPS×100↓ | SSIM×10↑ | PSNR↑ |
|---|---|---|---|---|---|---|---|---|
| Deter. | P2P | NP | .246 | .140 | 1.62 | 6.90 | 8.34 | 26.21 |
| Deter. | P2P | NT | .248 | .130 | 1.34 | 6.07 | 8.41 | 27.03 |
| Deter. | P2P | StyleD | .248 | .085 | 1.17 | 6.61 | 8.34 | 26.05 |
| Deter. | P2P | NMG | .249 | .087 | 1.32 | 5.59 | 8.47 | 27.05 |
| Deter. | P2P | PnP Inv | .250 | .095 | 1.17 | 5.46 | 8.48 | 27.22 |
| Deter. | P2P | h-Edit-D | .253 | .147 | 1.17 | 4.85 | 8.54 | 27.87 |
| Random | None | EF | .254 | .122 | 1.29 | 6.09 | 8.37 | 25.87 |
| Random | None | LEDITS++ | .254 | .113 | 2.34 | 8.88 | 8.11 | 23.36 |
| Random | None | h-Edit-R | .255 | .148 | 1.28 | 5.55 | 8.46 | 26.43 |
| Random | P2P | EF | .255 | .126 | 1.51 | 5.70 | 8.40 | 26.30 |
| Random | P2P | h-Edit-R | .256 | .159 | 1.45 | 5.08 | 8.50 | 26.97 |
不同 inversion / attention 组分别比较。h-Edit-D 在 deterministic + P2P 组最强;h-Edit-R + P2P 在 random + P2P 组更强。无 P2P 更适合添加/删除,P2P 更利于颜色/纹理。
| Method | ID↑ | Expr↓ | Pose↓ | LPIPS↓ | FID↓ |
|---|---|---|---|---|---|
| FaceShifter | .70 | 2.39 | 2.81 | .08 | 10.16 |
| MegaFS | .34 | 2.88* | 7.71 | .15 | 27.07 |
| AFS | .47 | 2.92 | 4.68 | .13 | 17.55 |
| DiffFace | .61 | 3.04 | 4.35 | .10 | 11.89 |
| EF | .74 | 3.10 | 4.12 | .06 | 20.78 |
| h-Edit-R | .80 | 2.76 | 3.78 | .04 | 17.68 |
| h-Edit-R (3s) | .84 | 3.10 | 4.29 | .05 | 19.12 |
* MegaFS expression 只在可检测脸上计算。3-step 提升 ID,但 expression、pose、LPIPS、FID 全部劣于 1-step。主 reward 与主 ID 同用 ArcFace,存在适应评价风险。
| Model / Metric | FaceShifter | MegaFS | AFS | DiffFace | EF | h-R | h-R 3s |
|---|---|---|---|---|---|---|---|
| ArcFace Res34 / cos↑ | .54 | .33 | .44 | .56 | .50 | .52 | .55 |
| VGG-Face / L2↓ | .99 | 1.12 | 1.03 | .96 | 1.02 | 1.00 | .97 |
| FaceNet128 / L2↓ | .83 | 1.02 | .86 | .77 | .83 | .80 | .77 |
| FaceNet512 / L2↓ | .81 | 1.01 | .87 | .77 | .83 | .81 | .77 |
DiffFace 在四个外部表示中最好或并列最好;h-Edit-R 3s 多为第二或并列,FaceShifter 在 Res34 上 .54 高于 1-step 的 .52。
| Attn. | Inv. | Method | CLIP | Local | DINO×100↓ | LPIPS×100↓ | SSIM×10↑ | PSNR↑ |
|---|---|---|---|---|---|---|---|---|
| MasaCtrl | Deter. | PnP Inv | .243 | .068 | 2.47 | 8.79 | 8.13 | 22.64 |
| MasaCtrl | Deter. | h-Edit-D | .243 | .071 | 2.38 | 8.62 | 8.16 | 22.85 |
| MasaCtrl | Random | EF | .241 | .059 | 2.75 | 8.57 | 8.15 | 22.49 |
| MasaCtrl | Random | h-Edit-R | .242 | .065 | 2.46 | 8.42 | 8.18 | 22.68 |
| PnP | Deter. | NP | .250 | .152 | 1.84 | 8.55 | 8.19 | 25.05 |
| PnP | Deter. | NT | .251 | .144 | 1.58 | 7.94 | 8.24 | 25.53 |
| PnP | Deter. | NMG | .253 | .101 | 2.08 | 9.96 | 8.02 | 23.20 |
| PnP | Deter. | PnP Inv | .253 | .109 | 1.75 | 9.29 | 8.15 | 24.18 |
| PnP | Deter. | h-Edit-D | .254 | .158 | 1.51 | 7.28 | 8.33 | 25.68 |
| PnP | Random | EF | .253 | .118 | 1.48 | 6.87 | 8.32 | 24.77 |
| PnP | Random | h-Edit-R | .255 | .147 | 1.39 | 5.97 | 8.43 | 25.75 |
[原图占位] h-Edit-D + P2P 与 deterministic inversion + P2P baselines 的额外视觉比较,补充 Table 1 的困难编辑案例。
[原图占位] h-Edit-R、EF 与 LEDITS++ 在 P2P 下的额外结果,显示编辑成功与背景保留差异。
[原图占位] h-Edit-R、EF、LEDITS++ 无 P2P 的额外结果;与 Figure 6 联合说明 attention control 对颜色、纹理与添加/删除的影响。
[原图占位] Face baselines 的额外对比,图下 ID 使用外部 ArcFace ResNet34,呼应 Table 2 的跨 encoder 复核。
[原图占位] style weight sweep:h-Edit-R + P2P 范围 .1–1.0,EF + P2P 范围 1.1–2.0;曲线包含 style loss、Local CLIP、LPIPS,没有精确点表。
[原图占位] EF 的 style weight 1.4–1.8 与 h-Edit 的 .4–.8 视觉序列,展示风格增强与保真下降的权衡。
[原图占位] 文本 + 风格组合的额外结果,图下给 style loss;不同方法用各自视觉调优后的 weight。
[原图占位] 固定 \(w_{\mathrm{edit}}=7.5,w_{\mathrm{orig}}=1\),扫描 \(\hat w_{\mathrm{orig}}=1,3,5,7,9\),过高值会删除过多原图信息。
[原图占位] 联合扫描 \(w_{\mathrm{edit}}\) 与 \(\hat w_{\mathrm{orig}}\)。更大编辑权重能处理困难案例,同时可能损害无关区域。
[原图占位] implicit 50 steps 的 1/2/3 inner-loop 与 explicit 200 steps 定性比较;没有 NFE 或 wall-time 等价实验。
[原图占位] 无 P2P、25 sampling steps 下 explicit 与 implicit 的逐例比较,补充 Table 5 的指标取舍。
[原图占位] P2P、25 sampling steps 下 explicit 与 implicit 的逐例比较,两种形式各有胜负。
[原图占位] h-Edit-R 3-step 的 masked / unmasked face outputs。无 mask 时仍有轻微背景模糊,主表则使用 mask 后处理。
| \(\hat w\) | CLIP | Local | DINO×100↓ | LPIPS×100↓ | SSIM×10↑ | PSNR↑ |
|---|---|---|---|---|---|---|
| 1 | .256 | .118 | 1.64 | 6.00 | 8.38 | 25.75 |
| 3 | .255 | .137 | 1.52 | 5.49 | 8.44 | 26.36 |
| 5 | .256 | .159 | 1.45 | 5.08 | 8.50 | 26.97 |
| 7 | .254 | .173 | 1.60 | 5.22 | 8.51 | 26.94 |
| 9 | .241 | .172 | 2.30 | 6.44 | 8.40 | 26.03 |
\(\hat w=7\) 的 Local CLIP 更高;推荐 5 是多指标折衷。超过 \(w_{\mathrm{edit}}=7.5\) 的 9 破坏重建。
| Attn. | Steps | Form | CLIP | Local | DINO×100↓ | LPIPS×100↓ | SSIM×10↑ | PSNR↑ |
|---|---|---|---|---|---|---|---|---|
| None | 25 | explicit | .252 | .139 | 1.10 | 5.10 | 8.49 | 26.79 |
| None | 25 | implicit | .255 | .148 | 1.39 | 5.98 | 8.41 | 25.77 |
| None | 50 | explicit | .253 | .141 | 1.10 | 5.07 | 8.51 | 27.00 |
| None | 50 | implicit | .255 | .148 | 1.28 | 5.55 | 8.46 | 26.43 |
| P2P | 25 | explicit | .254 | .153 | 1.38 | 5.04 | 8.50 | 26.81 |
| P2P | 25 | implicit | .255 | .150 | 1.38 | 5.03 | 8.50 | 26.88 |
| P2P | 50 | explicit | .256 | .158 | 1.47 | 5.10 | 8.50 | 26.85 |
| P2P | 50 | implicit | .256 | .159 | 1.45 | 5.08 | 8.50 | 26.97 |
无 P2P 时 implicit 编辑性较高,explicit 的 DINO / LPIPS 保真较高;P2P 25 steps 时 explicit Local .153 高于 implicit .150。选择 implicit 的主要理由是 \(K\gt1\)。Figure 14 的 200-step explicit 对比只有 qualitative 证据。
| Inv. | Attn. | Method | Time |
|---|---|---|---|
| Deter. | P2P | NP | 21.68 |
| Deter. | P2P | NT | 186.84 |
| Deter. | P2P | StyleD | 467.16 |
| Deter. | P2P | NMG | 35.67 |
| Deter. | P2P | PnP Inv | 37.65 |
| Deter. | P2P | h-Edit-D | 48.63 |
| Random | None | EF | 23.20 |
| Random | None | LEDITS++ | 18.31 |
| Random | None | h-Edit-R | 33.07 |
| Random | P2P | EF | 32.95 |
| Random | P2P | h-Edit-R | 50.21 |
| FaceShifter | 1.31 |
| MegaFS | 2.29 |
| AFS | 1.03 |
| DiffFace | 46.42 |
| EF | 26.11 |
| h-Edit-R | 26.34 |
| h-Edit-R 3s | 51.36 |
| EF + P2P | 44.32 |
| h-Edit-R + P2P | 50.68 |
V100 32GB。h-Edit-D 比 PnP Inv 多 10.98 秒;Face 3-step 为 1-step 的约 1.95 倍。无 P2P 跳过 15 steps,名义 steps 与实际 forward 成本不同。
文本 inner-loop 的 UNet 全在 torch.no_grad()。三种 CFG noise 构成 correction,不计算 UNet Jacobian。
仅 opt_step > 0 使用 F.l1_loss(current,base);梯度乘 correction RMS / gradient RMS 与 reconstruction weight。它和论文指数 L2 专家不同,\(K=1\) 无 shrink。
每轮先 ArcFace,再重算 detach noise,然后 LPIPS;tm1==0 将 inner-loop 改为 0。
调用 h-Edit / EF 时传 soft_face_mask=None,reward gradient 不受 mask 限制;mask 只在最后恢复背景。
P2P 在最后一个 inner-loop 保存 attention map,再执行 callback;风格组合关闭 local blend。
Python 3.8、PyTorch 1.13.1、Diffusers 0.18.0、Transformers 4.31.0;硬件 V100 32GB。
Appendix A.3 Eq. 64 缺 \(\log\),Eq. 65 的 score 符号与 Eq. 57 / 66 不一致。保持时间索引自洽时,显式系数为 \(\gamma_t^{\mathrm{E}}=-b_t\sigma_t\),隐式系数为 \(\gamma_t^{\mathrm{I}}=-b_t\sigma_{t-1}\);两者分别抵消对应 score 分母并得到 \(+b_tf_\theta\)。